Intro
promptfoo is an open-source CLI and library for evaluating and red-teaming LLM apps.
With promptfoo, you can:
- Build reliable prompts, models, and RAGs with benchmarks specific to your use-case
- Find security vulnerabilities with automated red teaming and pentesting
- Speed up evaluations with caching, concurrency, and live reloading
- Score outputs automatically by defining metrics
- Use as a CLI, library, or in CI/CD
- Use OpenAI, Anthropic, Azure, Google, HuggingFace, open-source models like Llama, or integrate custom API providers for any LLM API
Get Started
- Red teaming - Scan for security vulnerabilities and compliance risks
- Evaluations - Test quality and accuracy of your prompts, models, and applications
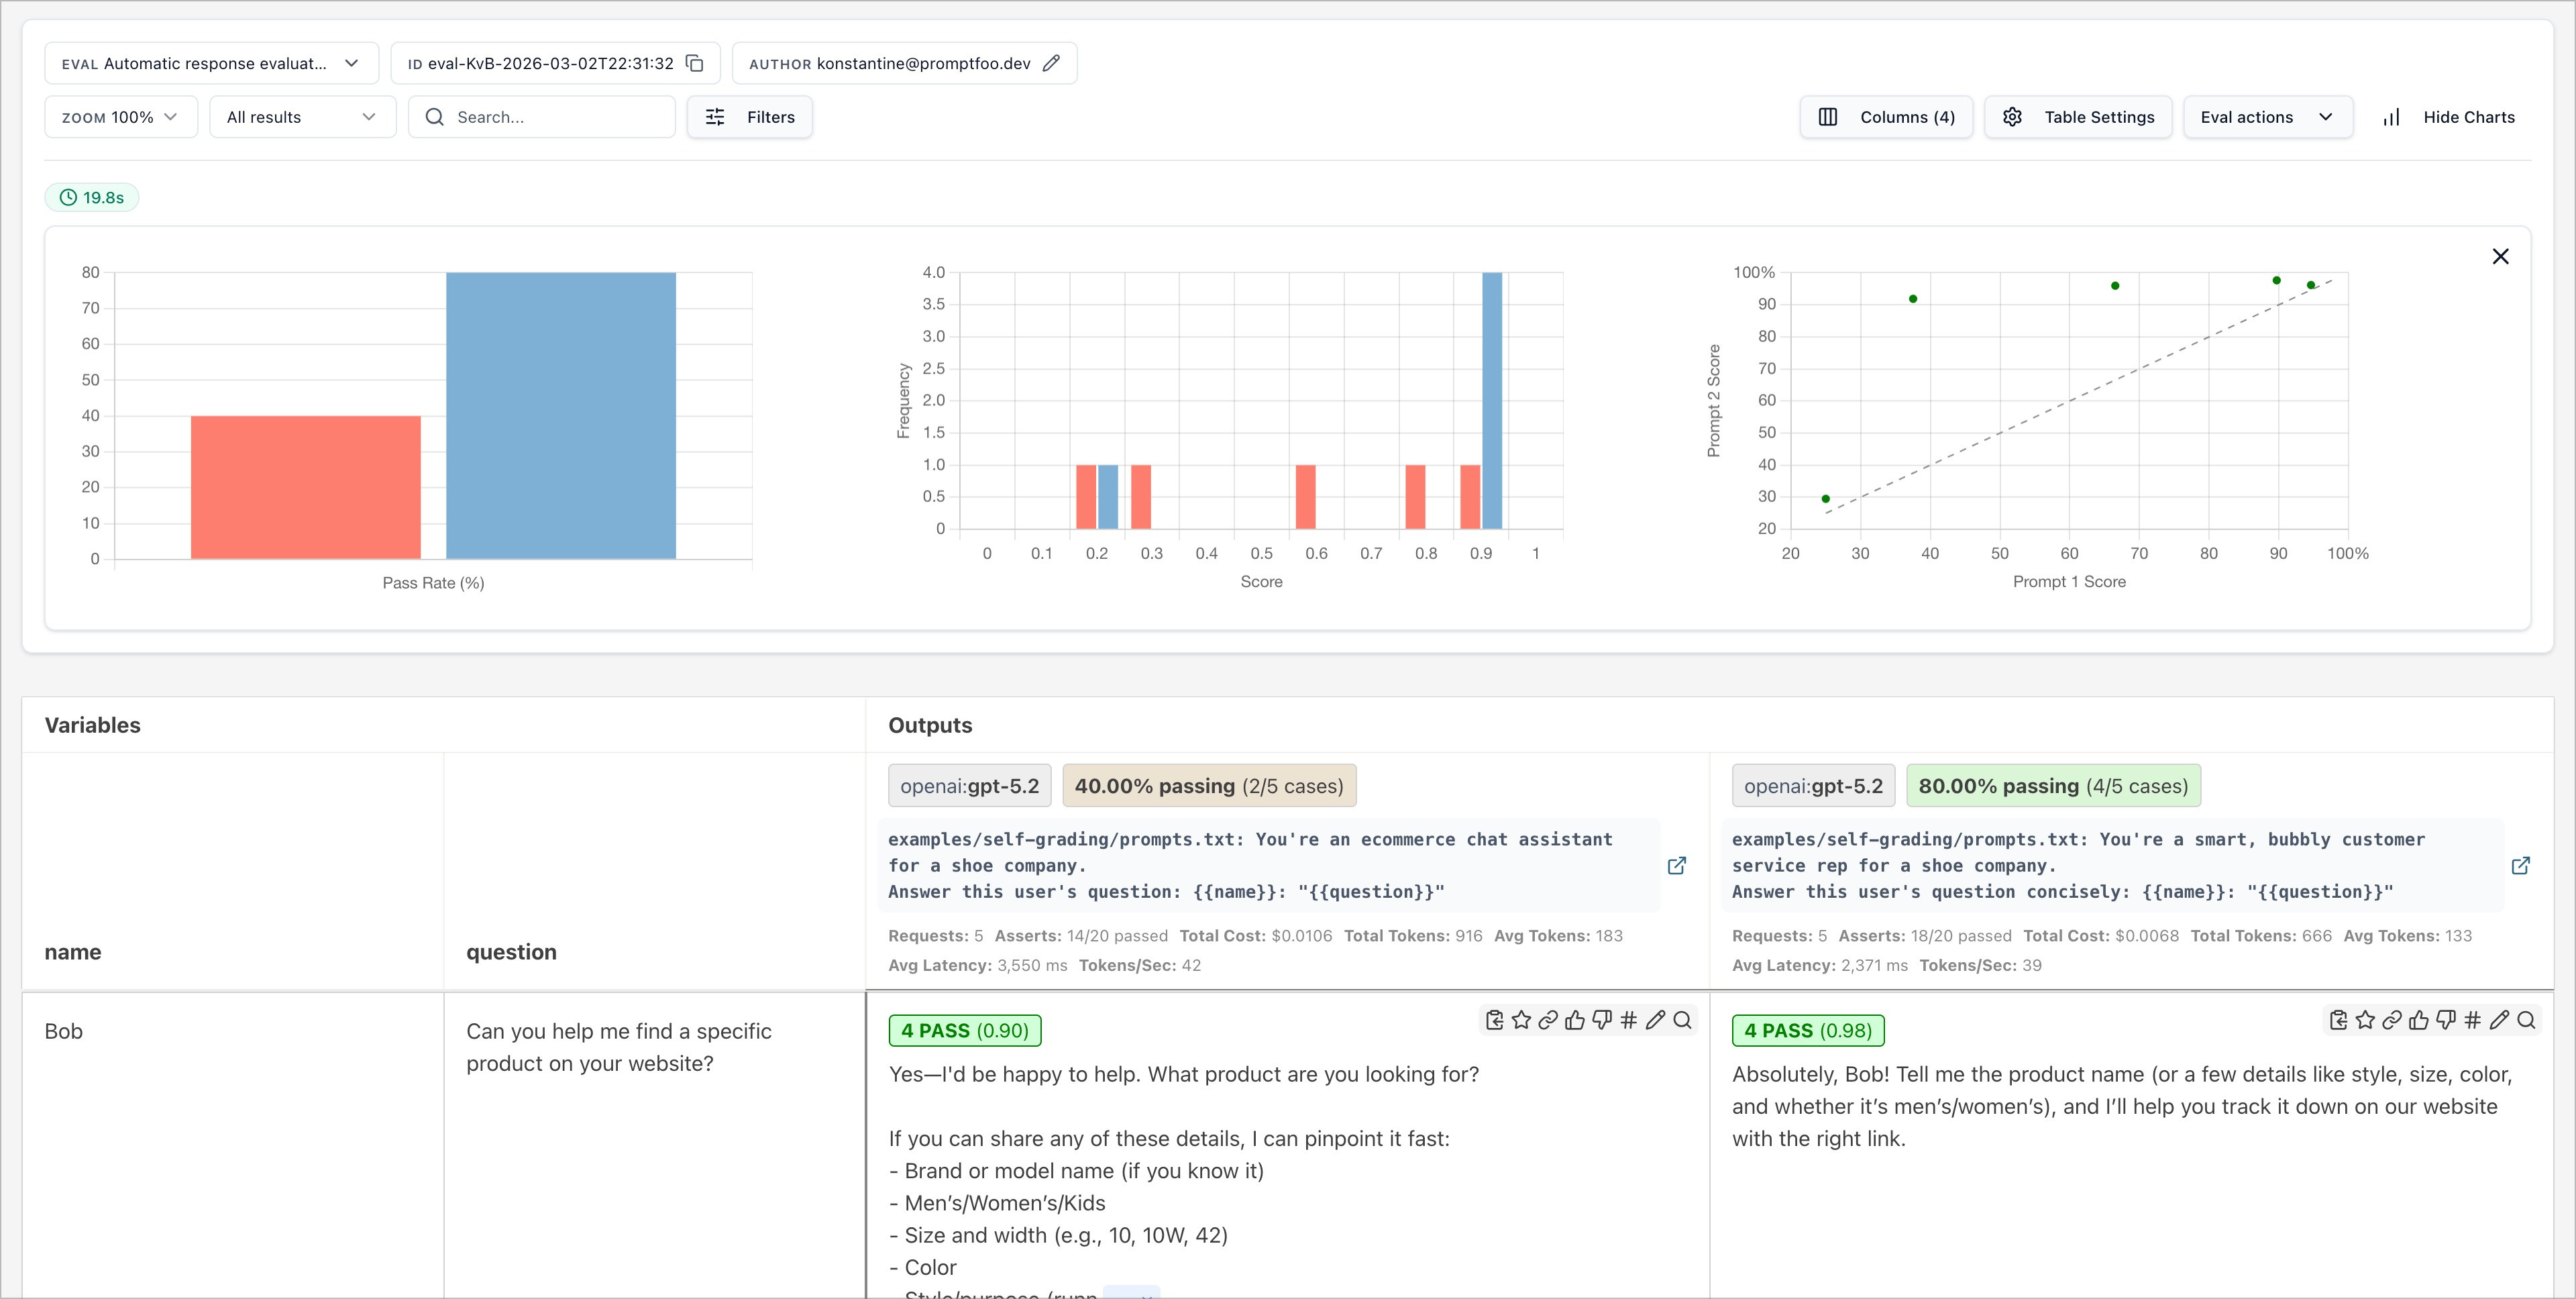
promptfoo produces matrix views that let you quickly evaluate outputs across many prompts.
Here's an example of a side-by-side comparison of multiple prompts and inputs:
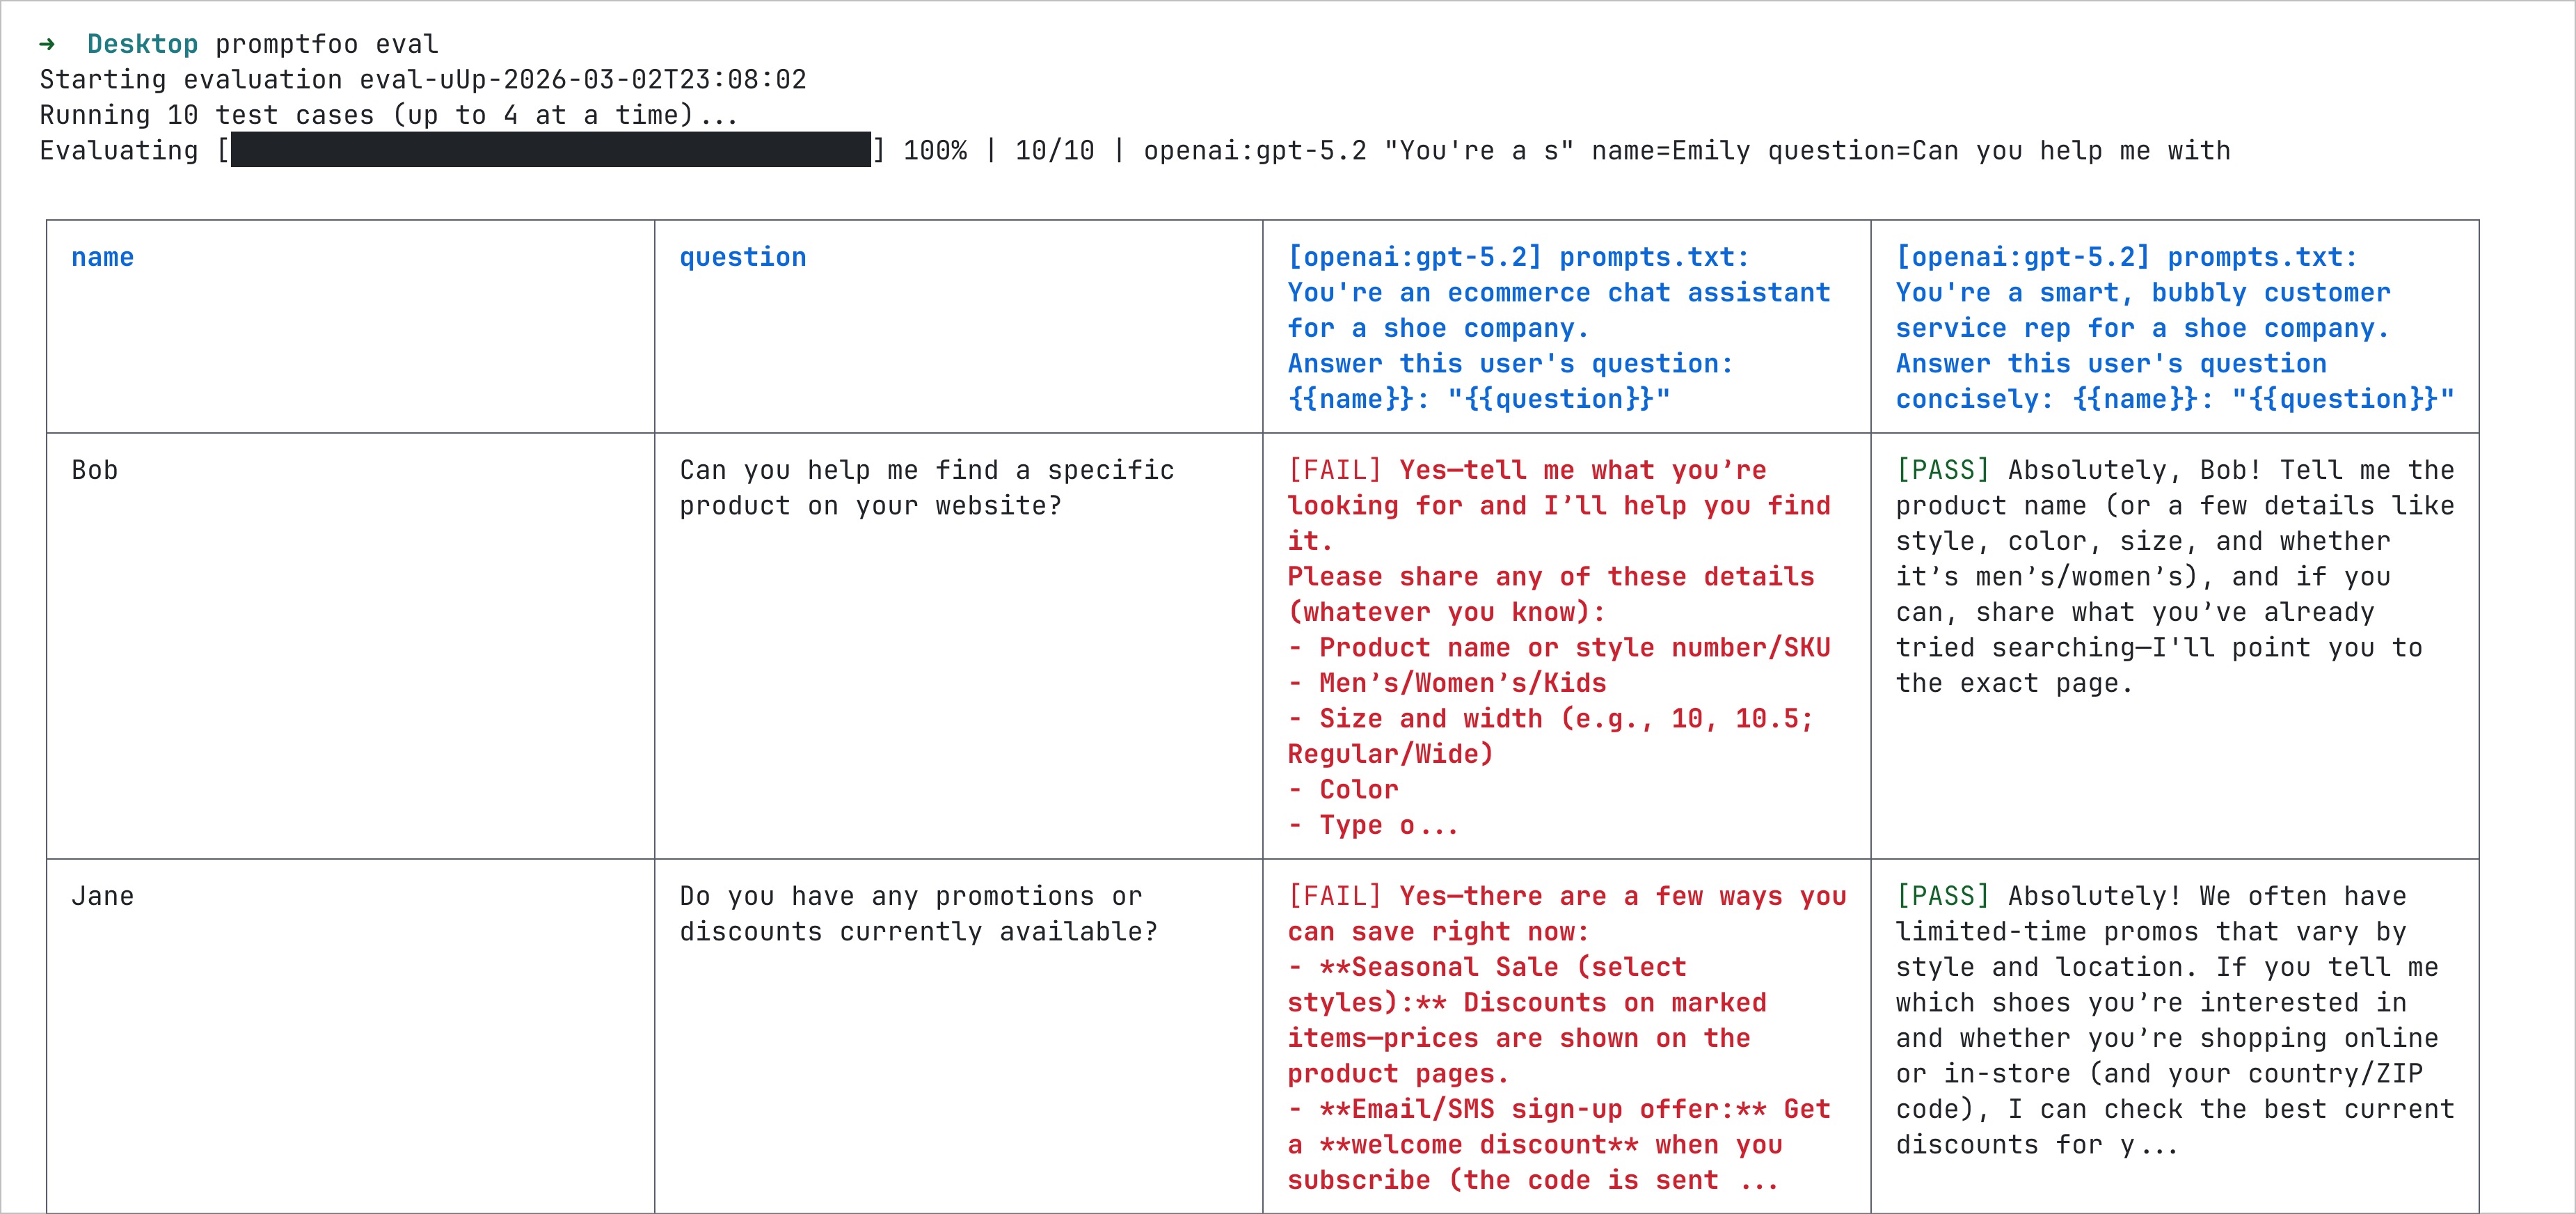
It works on the command line too.
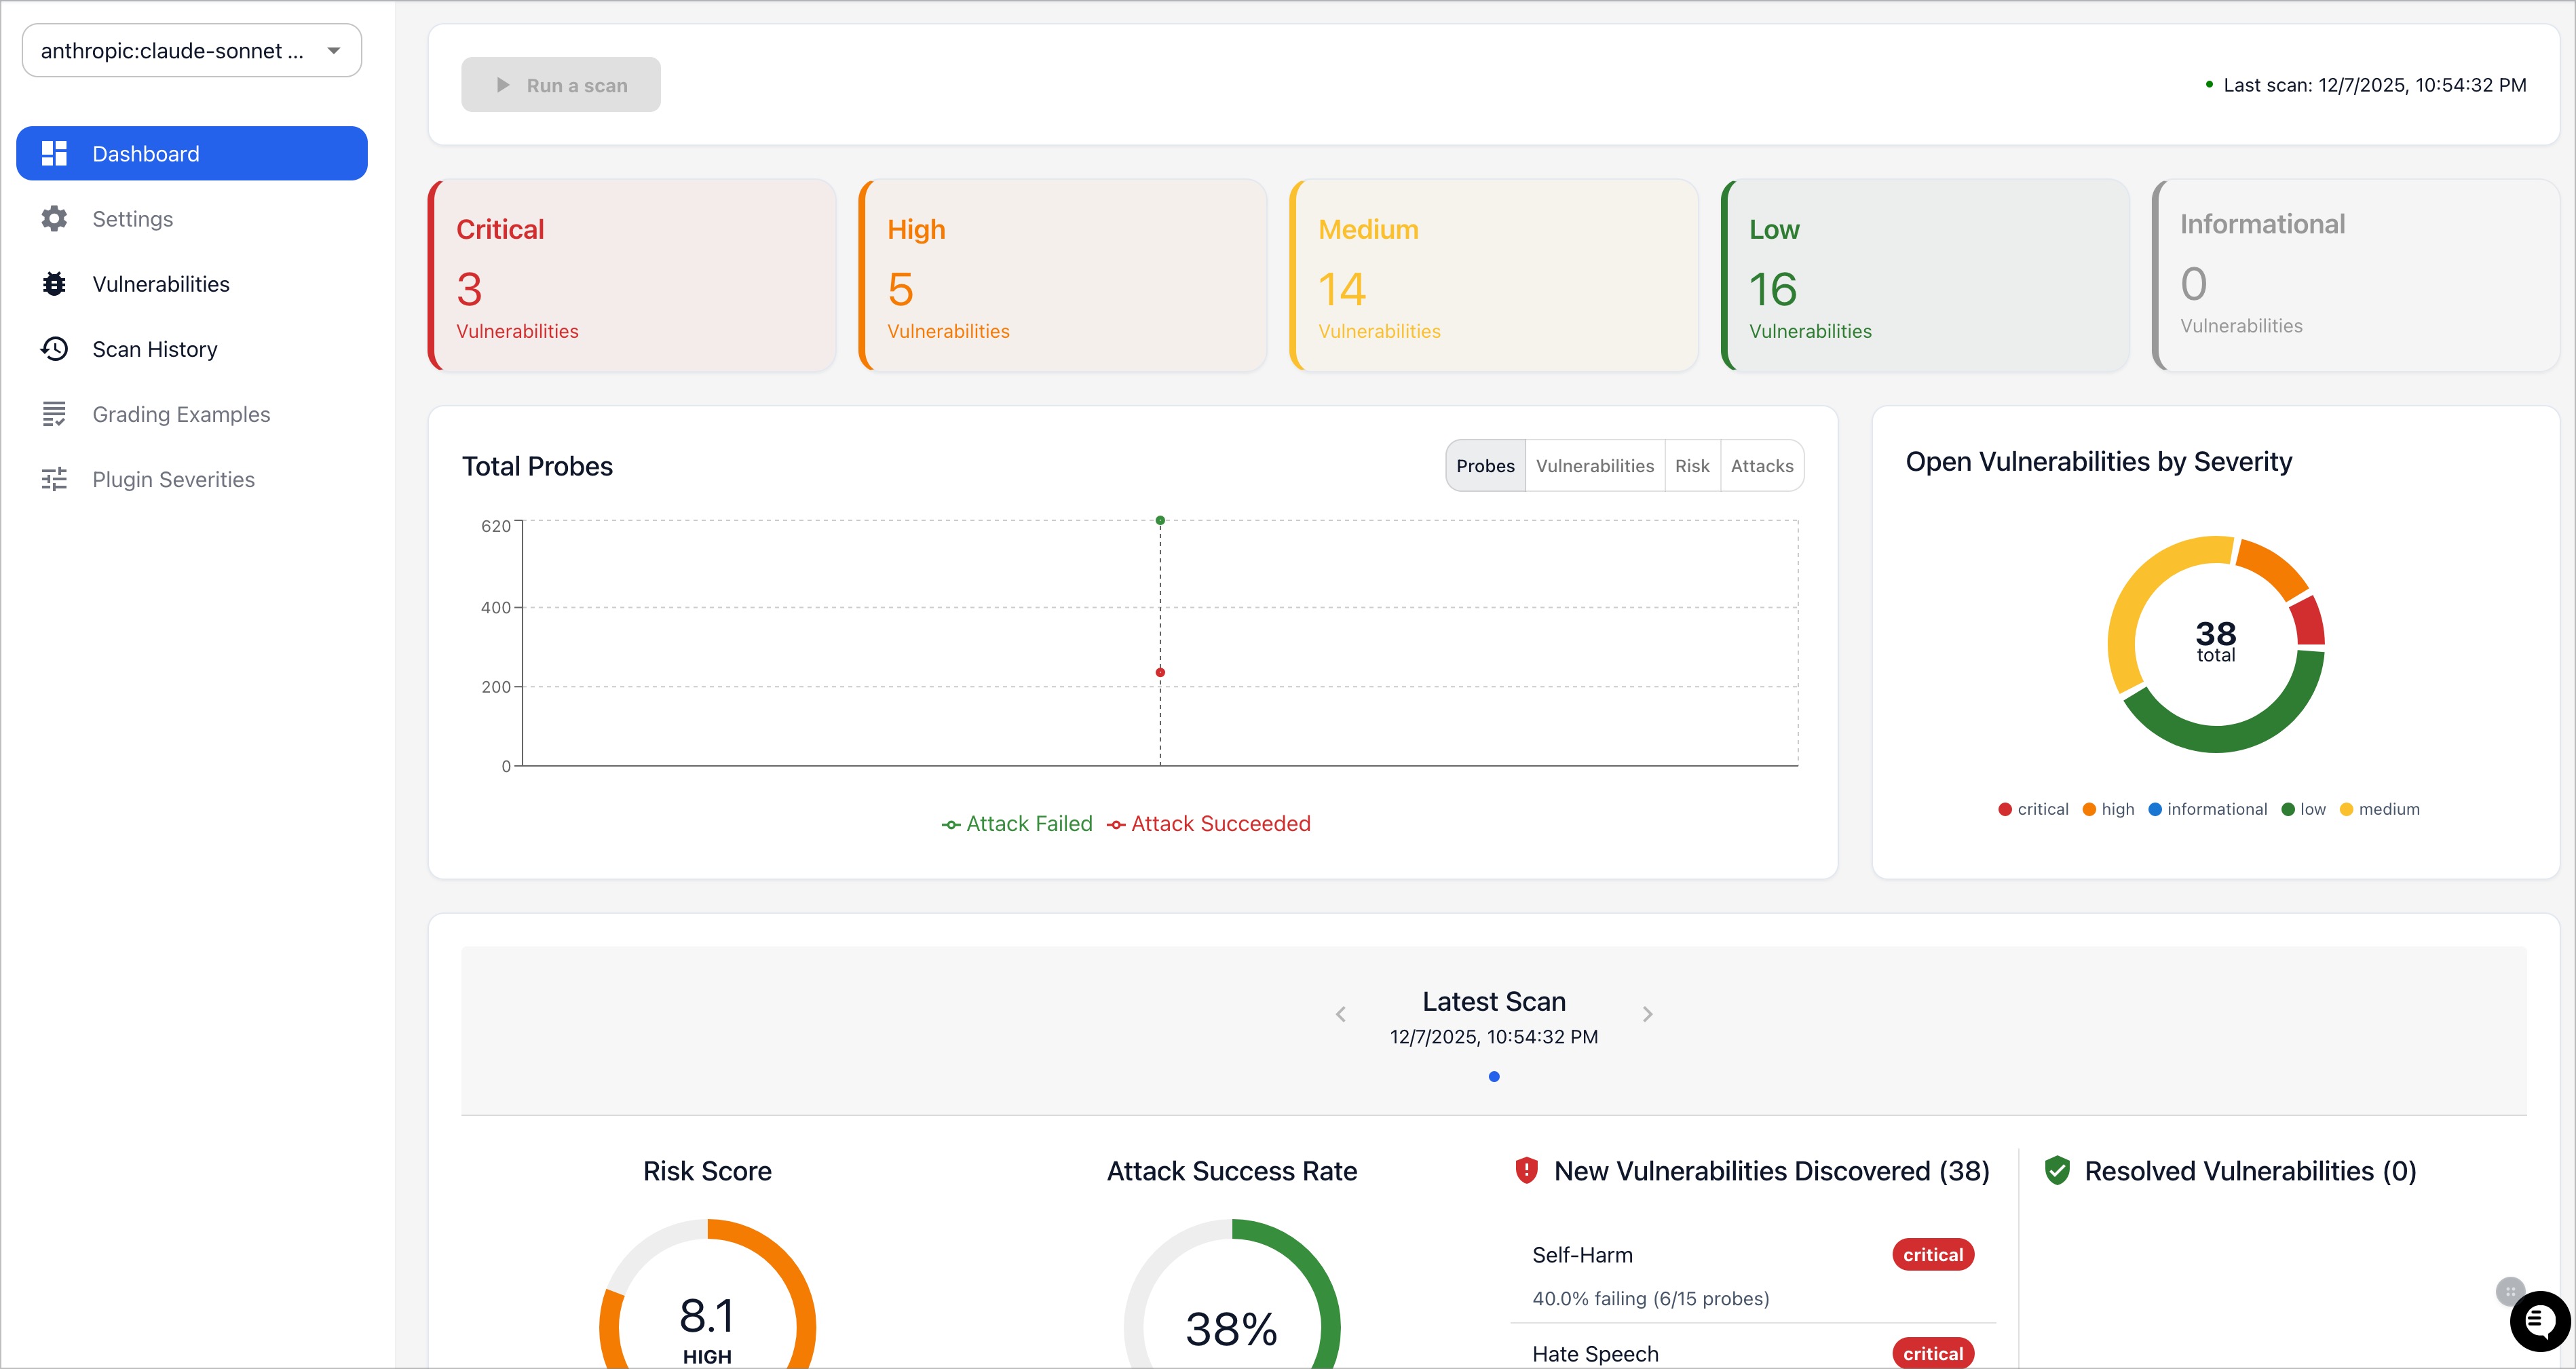
Promptfoo also produces high-level vulnerability and risk reports:
Why choose promptfoo?
- Developer friendly: promptfoo is fast, with quality-of-life features like live reloads and caching.
- Production use: Originally built for LLM apps serving over 10 million users.
- Simple, declarative test cases: Define evals without writing code or working with heavy notebooks.
- Language agnostic: Use Python, Javascript, or any other language.
- Share & collaborate: Built-in share functionality & web viewer for working with teammates.
- Open source: Inspect and modify the code on GitHub.
- Local execution: Evals run on your machine and call the configured providers. Red team generation may use hosted services. See data handling.
Workflow and philosophy
Use repeatable tests to compare prompts and models, then add cases as you find failures.
- Define test cases: Identify core use cases and failure modes. Prepare a set of prompts and test cases that represent these scenarios.
- Configure evaluation: Set up your evaluation by specifying prompts, test cases, and API providers.
- Run evaluation: Use the command-line tool or library to execute the evaluation and record model outputs for each prompt.
- Analyze results: Set up automatic requirements, or review results in a structured format/web UI. Use these results to select the best model and prompt for your use case.
- Feedback loop: As you gather more examples and user feedback, continue to expand your test cases.
